Jenkins gives you two ways to develop your pipeline code: scripted and declarative.
The scripted pipeline (also known as the “traditional” pipeline) is based on Groovy as its domain-specific language. The declarative pipeline, on the other hand, offers a simplified and friendlier syntax, with dedicated statements for defining it and no need to learn Groovy.
Version 2.5 of the Jenkins Pipeline plugin introduced support for the declarative pipeline.
In this article, we will go over all the available directives for developing declarative pipeline scripts, which will make its capabilities clear.
Declarative Pipeline Syntax
A valid declarative pipeline must be defined with the pipeline statement and must include the following required sections:
- agent
- stages
- stage
- steps
In addition, these directives are available:
- environment (defined at the pipeline or stage level)
- input (defined at the stage level)
- options (defined at the pipeline or stage level)
- parallel
- parameters
- post
- script
- tools
- triggers
- when
Now we will describe each of the listed directives/sections, starting with the required ones.
agent
Jenkins provides the ability to run distributed builds by delegating them to “agent” nodes. This lets you run multiple projects from a single instance of the Jenkins server, while the workload is distributed to its agents. The details of how to configure the controller/agent mode are beyond the scope of this blog. See Jenkins distributed builds for more information.
Agents should be labeled with tags so they can be identified easily from one another. For example, nodes can be labeled by their platform (Linux, Windows, etc.), their version or their location. The “agent” section configures which nodes the pipeline can run on. Specifying agent any means Jenkins will run the job on any available node.
An example of its use could be:
pipeline {
    agent any
...
}
stages
This section allows generating different stages in the pipeline, which will be displayed as different segments when the job runs.
An example pipeline containing a stages statement:
pipeline {
    agent any
    stages {
        ...
    }
}
stage
At least one “stage” section must be defined in the “stages” section. It will contain the work the pipeline will perform. Stages must be named, because Jenkins will display each stage in the interface, as shown below:
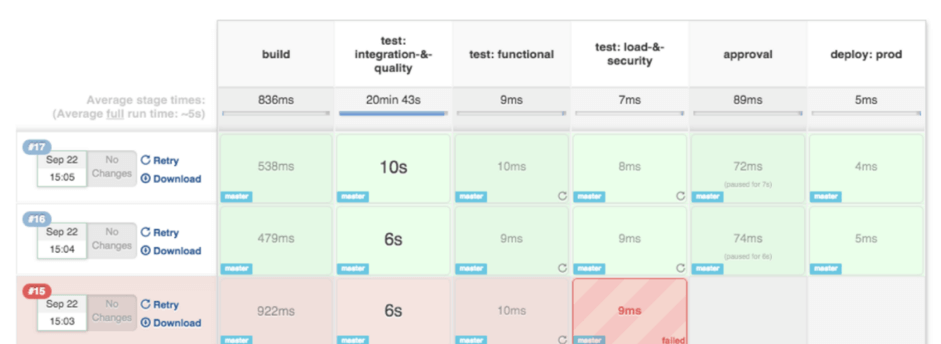
Jenkins splits the pipeline execution graphically according to the defined stages, and displays their duration and whether they succeeded.
The pipeline script of the previous image looks like this:
pipeline {
    agent any
    stages {
        stage ('build') {
            ...
        }
        stage ('test: integration-&-quality') {
            ...
        }
        stage ('test: functional') {
            ...
        }
        stage ('test: load-&-security') {
            ...
        }
        stage ('approval') {
            ...
        }
        stage ('deploy:prod') {
            ...
        }
    }
}
steps
The last required section is “steps”, which is defined inside a “stage”. At least one step must be defined in the “steps” section.
For Linux and MacOS, using the shell is supported. Here is an example:
steps {
    sh 'echo "A one line step"'
    sh '''
    echo "A multiline step"'
    cd /tests/results
    ls -lrt
    '''
}
For Windows, bat or PowerShell can be used, as shown below:
steps {
    bat "mvn clean test -Dsuite=SMOKE_TEST -Denvironment=QA"
    powershell ".\funcional_tests.ps1"
}
The other, non-required directives are explained in the following paragraphs.
environment
This directive can be defined at the stage or pipeline level, which determines the scope of its definition. When “environment” is used at the “pipeline” level, its definitions are valid for all pipeline steps. Conversely, if it is defined in a “stage”, it is only valid for that specific stage.
An example use of this directive:
At the “pipeline” level:
pipeline {
    agent any
    environment {
        OUTPUT_PATH = './outputs/'
    }
    stages {
        stage ('build') {
        ...
    }
    ...
    }
}
At the “stage” level:
pipeline {
    agent any
    stages {
        stage ('build') {
            environment {
                OUTPUT_PATH = './outputs/'
            }
            ...
        }
        ...
    }
}
input
The “input” directive is defined at the stage level and provides the ability to prompt for input. The stage will be paused until the user confirms manually.
The following configuration options are available for this directive:
- message: this is a required option, which specifies the message to display to the user.
- id: an optional identifier. By default, the “stage” name is used.
- ok: optional text for the “OK” button.
- submitter: an optional list of users or external group names allowed to submit the input. By default, any user is allowed.
- submitterParameter: the optional name of an environment variable to be set with the submitter’s name (if it exists).
- parameters: an optional list of parameters that the submitter will provide.
This is an example pipeline containing this directive:
pipeline {
    agent any
    stages {
        stage ('build') {
            input{
               message "Press Ok to continue"
               submitter "user1,user2"
                parameters {
                   string(name:'username', defaultValue: 'user', description: 'Username of the user pressing Ok')
                }
            }
            steps {
                echo "User: ${username} said Ok."
            }
        }
    }
}
options
Defined at the pipeline level, this directive groups specific options for the entire pipeline. The available options are:
- buildDiscarder
- disableConcurrentBuilds
- overrideIndexTriggers
- skipDefaultCheckout
- skipStagesAfterUnstable
- checkoutToSubdirectory
- newContainerPerStage
- timeout
- retry
- timestamps
See Jenkins declarative pipeline options for a complete reference on this.
For example, you can configure the pipeline to retry 3 times before failing, by doing the following:
pipeline {
    agent any
    options {
        retry(3)
    }
    stages {
        echo 'do something'
    }
}
parallel
Jenkins pipeline stages can nest other stages inside them, and those stages will be executed in parallel. This is done by adding the “parallel” directive to the script. Example usage:
stage('run-parallel-branches') {
    steps {
        parallel(
            a: {
                echo "Tests on Linux"
            },
            b: {
            echo "Tests on Windows"
            }
        )
    }
}
Starting with version 1.2 of the declarative pipeline, a new syntax was introduced that makes the use of parallel syntax more declarative.
The previous script rewritten using this new syntax looks like this:
pipeline {
    agent none
    stages {
        stage('Run Tests') {
            parallel {
                stage('Test On Windows') {
                    agent {
                        label "windows"
                    }
                steps {
                    bat "run-tests.bat"
                }
                }
                stage('Test On Linux') {
                    agent {
                        label "linux"
                    }
                    steps {
                        sh "run-tests.sh"
                    }
                }
            }
        }
    }
}
Any of the pipelines above will look like this:
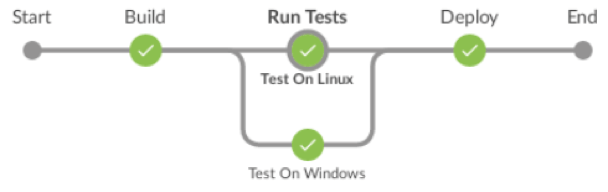
Since both scripts run platform-specific tests, they will run the tests on different nodes. If your Jenkins server has enough CPU, you can also use parallel to run stages at the same time on the same node by using multithreading.
There are some limitations when using parallel stages:
- A stage directive can have a parallel directive or a steps directive, but not both at the same time.
- A stage directive inside a parallel directive cannot nest another parallel directive; only steps are allowed.
- A stage directive that has a parallel directive inside it cannot define “agent” or “tools” directives.
parameters
This directive allows you to define the list of parameters to be used in the script. The parameters should be provided once the pipeline is triggered. It should be defined at the “pipeline” level, and only one such directive is allowed in the whole pipeline.
Strings and booleans are the valid parameter types you can use.
pipeline {
    agent any
    parameters {
        string(name: 'user', defaultValue: 'John', description: 'A user that triggers the pipeline')
    }
    stages {
        stage('Trigger pipeline') {
            steps {
                echo "Pipeline triggered by ${params.USER}"
            }
        }
    }
}
post
post can be added at the pipeline level or on each stage, and the statements it contains are executed once the stage or pipeline is complete. Several post conditions can be used to control whether the post is executed:
- always: the steps are executed regardless of the completion status.
- changed: executed only when the completion result is different from the status of the last run.
- fixed: executed only when the completion result is success and the last run failed.
- regression: executed only when the current execution failed, was aborted or is unstable, and the previous run was successful.
- aborted: the steps are executed only when the pipeline or stage is aborted.
- failure: the steps are executed only when the pipeline or stage fails.
- success: the steps are executed only when the pipeline or stage succeeds.
- unstable: the steps are executed only when the pipeline or stage is unstable.
Since the statements contained in the pipeline post run at the end of the script, cleanup tasks or notifications, among other things, can be performed here.
pipeline {
    agent any
    stages {
        stage('Some steps') {
            steps {
                echo 'do something'
            }
        }
    }
    post {
        always {
            echo "Pipeline finished"
            bat './performCleanUp.bat'
        }
    }
}
script
This step is used to add scripted pipeline statements to a declarative pipeline, thus providing more functionality. This step must be included at the “stage” level.
Script blocks can be used multiple times for different projects. These blocks let you extend Jenkins functionality, and they can be implemented as shared libraries. More information on this can be found in Jenkins shared libraries. Likewise, shared libraries can be imported and used inside “script”, which extends the pipeline’s functionality.
Next, we will provide example pipelines. The first has only one block containing a piece of scripted pipeline code, while the second will show how to import and use a shared library:
pipeline {
    agent any
    stages {
        stage('Sample') {
            steps {
                echo "Scripted block"
                script {

                }
            }
        }
    }
}
For more information on this topic, see the article on how to use the Jenkins scripted pipeline.
tools
The “tools” directive can be added at the pipeline level or the stage level. It allows you to specify the Maven, JDK or Gradle version to be used in the script. Any of these tools must be configured in the “Global Tool Configuration” Jenkins menu, and at the time of writing this, all three tools are supported.
In addition, Jenkins will try to install the listed tools if they are not already installed. By using this directive, you can ensure that the specific version required by the project is installed.
pipeline {
    agent any
    tools {
        maven 'apache-maven-3.0.1'
    }
    stages {
         echo 'do something'
    }
}
triggers
Triggers allow Jenkins to trigger the pipeline automatically by using any one of the following available means:
- cron: by using cron syntax, it defines when to re-trigger the pipeline.
- pollSCM: by using cron syntax, it allows you to define when Jenkins checks the source repository for new updates. If a change is detected, the pipeline will be re-triggered. (Available as of Jenkins 2.22).
- upstream: takes Jenkins jobs and threshold conditions as input. When any of the jobs in the list meets the threshold condition, the pipeline will be triggered.
An example pipeline with the available triggers looks like this:
pipeline {
    agent any
    triggers {
        //Execute weekdays every four hours starting at minute 0
        cron('0 */4 * * 1-5')
    }
    stages {
        ...
    }
}


pipeline {
    agent any
    triggers {
        //Query repository weekdays every four hours starting at minute 0
        pollSCM('0 */4 * * 1-5')
    }
    stages {
        ...
    }
}


pipeline {
    agent any
    triggers {
        //Execute when either job1 or job2 are successful
        upstream(upstreamProjects: 'job1, job2', threshold: hudson.model.Result.SUCCESS)
    }
    stages {
        ...
    }
}
when
Pipeline steps can be executed according to the conditions defined in the “when” directive. If the condition matches, the steps defined in the corresponding stage will be run. It should be defined at the stage level.
For the complete list of conditions and their descriptions, see the Jenkins declarative pipeline “when” directive.
For example, pipelines let you perform tasks on projects with multiple branches. This is known as a multi-branch pipeline, where specific actions can be taken according to the branch name (e.g. “master”, “feature*”, “development”, etc.). Here is an example pipeline that will run the steps of the master branch:
pipeline {
    agent any
    stages {
        stage('Deploy stage') {
            when {
                branch 'master'
            }
            steps {
                echo 'Deploy master to stage'
            }
        }
    }
}
The Last 2 Jenkins Declarative Pipeline Tips
Declarative pipeline syntax errors are reported at the beginning of the script. This is a great feature, because you don’t waste time until a step fails to realize a typo or a spelling mistake.
As mentioned earlier, pipelines can be written declaratively or in a scripted way. Moreover, the declarative approach is built on top of the scripted approach, and it can be easily extended by adding the “script” step.
Jenkins pipelines are already widely used in CI/CD environments. Whether you use a declarative or a scripted pipeline, both have several advantages. In this article, we have covered all the syntax elements of the declarative pipeline by writing example scripts. As we have already said, the declarative approach provides a friendlier syntax, with no need for Groovy knowledge.